
FLOATING POINT - SQUARE ROOT
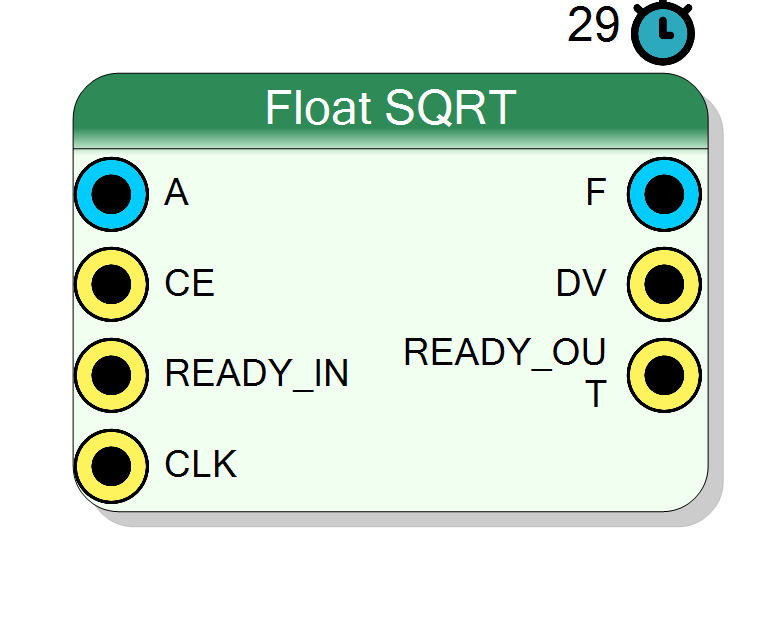
Computes the square root of IEEE-754 floating-point numbers with configurable throughput. Supports both single-precision (32-bit) and double-precision (64-bit) formats. Built on Xilinx Floating-Point IP core with blocking flow control, 29-cycle latency, and adjustable initiation interval (1-25 cycles).
Introduction
The block computes the square root of IEEE-754 floating-point inputs.
On every rising edge of CLK, if CE = 1, the square root unit computes
$$ \mathrm{F}(n) = \sqrt{\mathrm{A}(n)}, $$
where input A and output F follow IEEE-754 single or double
precision format.
The square root is implemented with the Xilinx floating_point IP core configured for Square_root operation using iterative algorithm with blocking flow control, fixed 29-cycle latency, and configurable initiation interval to trade area for throughput.
Pin Description
CE = 1 and READY_OUT = 1.
CE = 1, input A is accepted and square root computation begins. Can be tied to ‘1’ for continuous operation.
DV = 1.
Result = sqrt(A).
F contains a valid square root.
Asserts 29 clock cycles after corresponding CE = 1.
Properties
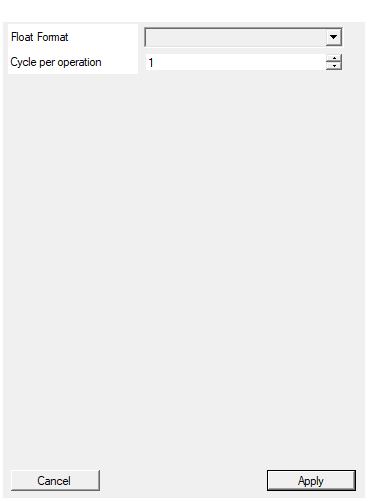
Select between single precision 32 bit and double precision 64 bit
Floating-point precision for both input and output:
- Single → 32-bit (8-bit exponent, 24-bit mantissa including implicit bit)
- Double → 64-bit (11-bit exponent, 53-bit mantissa including implicit bit)
The operation preserves the precision format end-to-end.
Default: Single
Options: Single Double
Number of clock cycles to execute a division. Set to 1 to perform division in realtime. Higher number reduce the area usage of the block
Initiation Interval (cycles per operation). Range: 1 - 25.
- 1 → Fully pipelined, maximum throughput, largest area
- 25 → Minimal area, throughput = 1/25 of maximum
Set to 1 for continuous streaming square root operations. Increase to reduce resource usage if throughput is not critical.
Default: 1
Range: 1 – 25
Functional description
The component computes the square root:
$$ F = \sqrt{A} $$
The implementation uses an iterative digit-recurrence algorithm with:
- Exponent halving ($e’ = e/2$)
- Mantissa square root via Newton-Raphson or similar iteration
- Result normalization
Special cases
IEEE-754 special value handling:
sqrt(0) = 0sqrt(1) = 1sqrt(x) = NaNforx < 0(domain error)sqrt(+Inf) = +Infsqrt(NaN) = NaN(NaN propagation)
Initiation Interval (II)
The Cycle per operation property sets the initiation interval:
- II = 1 → New operation every cycle (maximum throughput, largest area)
- II = 25 → New operation every 25 cycles (minimum area, reduced throughput)
Higher II values reduce hardware resources (especially logic and registers) at the cost of lower throughput. For continuous streaming, choose II = 1. For infrequent square roots, larger II saves area.
Timing
The IP has a fixed 29-cycle pipeline latency regardless of II:
| Clock cycle | Event |
|---|---|
| 0 | Input A presented with CE = 1 |
| 29 | Output F valid with DV = 1 |
With II = 1, a new operation can start every cycle (fully pipelined). With II > 1, the next operation must wait II cycles before starting.
Typical use cases
- RMS (root-mean-square) calculations
- Distance computation (Euclidean norm components)
- Standard deviation in statistics
- Magnitude normalization