
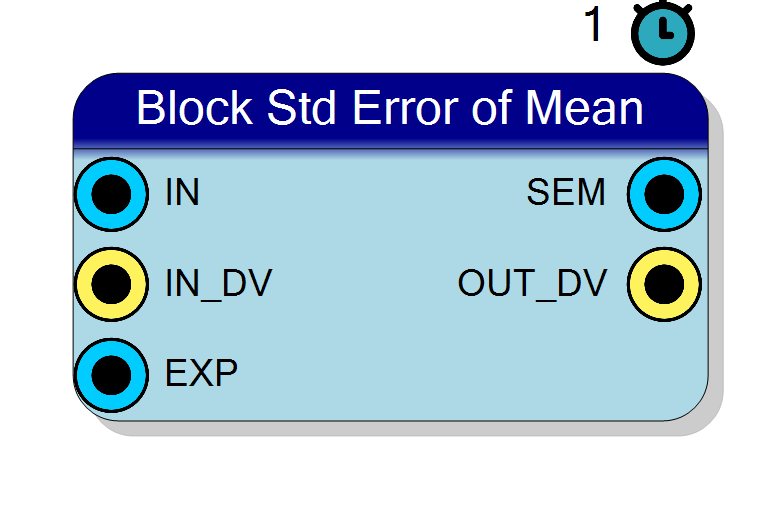
DSP - BLOCK STD ERROR OF MEAN
The standard error of the mean of a block of N consecutive samples, sem = sigma / sqrt(N): how far the BLOCK MEAN is expected to sit from the true mean of the process. It is the error bar to put on a Block Mean output, and the number that tells you whether averaging longer is still buying you anything. N is a power of two chosen at RUN TIME on the EXP input pin, so sqrt(N) is HALF A SHIFT and folds into the same radicand as the variance - 3EXP instead of the 2EXP a plain standard deviation uses. It therefore costs EXACTLY what Block Std Dev costs: one serial square of S1 and one serial square root, no divider, no extra multiplier and not one clock more, with odd exponents handled exactly because the halving happens INSIDE the root. The latency is L = 2 + (IN_SW + EXP + 1) + (RTW + 1) and 2^EXP >= L must hold or that block’s result is silently dropped. GIVE IT FRACTIONAL BITS: sem is small by construction. IN_DV is the only qualifier and there is deliberately no CE pin. Optional BUSY / INTEGRATING / SAMPLE_COUNT status outputs. Blocks of up to 2^20 samples out of the box, 2^31 if you ask for it.
Introduction
The Block Std Error of Mean block chops the input stream into consecutive blocks of N samples and, at the end of each block, publishes the standard error of the mean of that block:
$$ \sigma = \sqrt{\frac{1}{N}\sum_{i=0}^{N-1}\bigl(x_i-\bar{x}\bigr)^2}, \qquad \mathrm{SEM} = \frac{\sigma}{\sqrt{N}} $$
$\sigma$ here is the population standard deviation of the block - exactly the quantity Block Std Dev produces - and N is the block length.
N is a runtime input, not a property. You drive the exponent on the
EXP pin and the block size is $N = 2^{\mathrm{EXP}}$:
| EXP | N | EXP | N |
|---|---|---|---|
| 4 | 16 | 12 | 4096 |
| 6 | 64 | 16 | 65536 |
| 8 | 256 | 20 | 1048576 |
What a standard error is FOR
$\sigma$ answers “how much does the signal wander?”. The standard error answers a different and usually more actionable question: “how much does my MEASUREMENT of the average wander?”.
- It is the error bar on a Block Mean output. Latch
MEANfrom a Block Mean block andSEMfrom this one over the same block, and you have a value and its uncertainty, ready to publish or to threshold. - It tells you whether averaging longer still helps. Because
$\mathrm{SEM}\propto 1/\sqrt{N}$, quadrupling the block halves the error
bar - as long as the noise really is uncorrelated. Watch
SEMas you sweepEXP: while it keeps falling like $1/\sqrt{N}$ you are still winning; when it flattens out you have hit drift or correlated noise and a longer block is wasted time. - It is the natural acceptance criterion for a slow-control reading: keep
integrating until
SEMis below the tolerance you need, then stop. - It converts directly into a confidence interval - roughly $\bar{x}\pm 2,\mathrm{SEM}$ for 95% under the usual assumptions - which is what a CPU or an operator actually wants to see.
Why this is almost free
N is a power of two, so $\sqrt{N} = 2^{\mathrm{EXP}/2}$ and dividing by it is half a shift - which is exactly the sort of thing a square root can absorb. Everything folds into one radicand:
$$ \mathrm{sem}^2 = \frac{\mathrm{var}}{N} = \frac{\mathrm{var_num}}{N^3}, \qquad \mathrm{var_num} = N!\cdot! S_2 - S_1^2 $$
$$ \mathrm{root} = \sqrt{;\mathrm{var_num}\cdot 2^{,2(\mathrm{SEM_{fract}}+\mathrm{SQG}) - 2,\mathrm{IN_{fract}} - 3,\mathrm{EXP}};} $$
Compare Block Std Dev, which is the same core with $2,\mathrm{EXP}$ in
that exponent instead of $3,\mathrm{EXP}$: the extra EXP is the $/N$ that
turns the variance into the variance of the mean. That is the entire
difference. There is no divider, no extra multiplier and not one clock
more.
Odd exponents are exact. There is no $\sqrt{2}$ factor to approximate anywhere, because the halving happens inside the root - $3,\mathrm{EXP}$ is an integer shift for every EXP, odd or even.
Cost
Per clock: one multiplier for $x^2$ (unavoidable at one sample per clock) and two accumulators, $S_1$ and $S_2$. In the tail: one reused shift-add stage for the serial $|S_1|\cdot|S_1|$ and one reused compare-subtract stage for the square root, each taking one step per clock. What you pay for the tail is clocks, not multipliers - and there is no DSP in the tail at all.
Identical, to the flip-flop and to the clock, to Block Std Dev at the same output width.
When to use this instead of Block Statistics
The all-in-one Block Statistics block is not deprecated, but it does
not compute this statistic: its outputs include MEAN, VARIANCE,
STDDEV, RMS, SUM, SUM_SQ, min/max and the rest, but there is no
standard-error pin. The rule is therefore slightly different here:
- you want several statistics of the SAME block and the standard error - place a Block Statistics block for the rest and this block alongside it. They will each keep their own accumulators, which is the price of a statistic the all-in-one does not have.
- you want exactly one number - use this block on its own. Then you synthesise only that number: two accumulators, one serial squarer, one serial root, and nothing else reaches the synthesiser.
If what you really need is $\sigma$ rather than $\sigma/\sqrt{N}$, use Block
Std Dev (or Block Statistics’ STDDEV) - it is the same cost, and you can
divide by $\sqrt{N}$ in software when N is known.
Pin Description
IN_DV is high.
'1'. (There is deliberately no CE pin - to stall the block,
gate this.)
OUT_DV clock and on no other; it holds the previous
block’s result until then.
SEM is updated on this clock
and on no other. BUSY is still high here and falls on the next clock.
A block whose result was dropped for being too short produces no pulse
at all - that is the only symptom.
OUT_DV pulse, and it
falls on the clock after. On a continuous stream it simply stays high.
Present on the symbol only when Enable BUSY = YES.
BUSY high with INTEGRATING low is exactly the square-then-root
tail. On a continuous stream it dips for one clock per block boundary,
which makes it a free block marker. Present on the symbol only when
Enable INTEGRATING = YES.
How many samples have been accumulated so far in the current block: 1 after the first, N after the N-th. It is NOT cleared at the end of a block
- it HOLDS the final count through the tail and past
OUT_DV, until the first sample of the next block takes it back to 1, it reads N atOUT_DVonly when the input STOPS for the whole tail. On a CONTINUOUS stream the next block has already started by then, soOUT_DVshows how far into it the input has got, not N - the clock that always reads N is the oneINTEGRATINGfalls on - i.e. the N that the error bar refers to. OnlyRESETclears it to 0. Fixed 32 bits. Present on the symbol only when Enable SAMPLE_COUNT = YES.
Properties
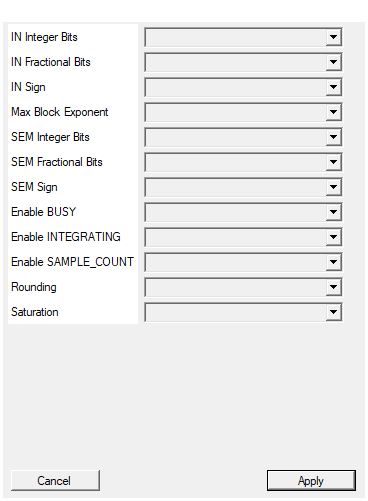
Number of INTEGER bits of the input sample (the sign, when present, uses one of them).
Integer bits of the input sample (the sign, when present, uses one of them). 1..64. Default 16.Default: 16
Options: 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Number of FRACTIONAL bits of the input sample, i.e. the bits to the right of the binary point. Total width = integer + fractional bits, and must not exceed 64.
Fractional bits of the input sample. 0..64. Total input width must be 2..64 bits. Default 0. They enter the radicand shift as $-2,\text{IN}_{fract}$, and every input bit - integer or fractional - adds one clock to the serial squarer and therefore one clock to the tail.Default: 0
Options: 0 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Select whether the input sample is signed (two’s complement) or unsigned.
SIGNED (two’s complement) or UNSIGNED input. Default SIGNED. An UNSIGNED input costs one extra bit internally, because a sample has to be promoted to signed before it can be accumulated - and that bit also adds one clock to the tail.Default: SIGNED
Options: UNSIGNED SIGNED
Largest block-size exponent the accumulators are sized for: the block can be up to 2^MaxBlockExponent samples long. The EXP input is clamped to this value at run time. Raising it widens the internal accumulators, and ON THE BLOCKS WHOSE SERIAL ENGINES ARE SIZED FROM THOSE ACCUMULATORS (Coefficient of Variation, SNR, Skewness, Kurtosis, Correlation, Autocorrelation, Linear Regression) it also LENGTHENS THE SERIAL TAIL – even when the runtime EXP is small. Keep it at the largest block you actually use. The default of 20 covers blocks of up to 1048576 samples.
Largest block-size exponent the accumulators are sized for: the block can be up to $2^{\text{MaxBlockExponent}}$ samples long, and theEXP input
is clamped to this value at run time. Raising it widens the internal $S_1$
and $S_2$ registers by one bit per unit. Unlike Block Coefficient of
Variation and Block SNR, it does not lengthen the tail here - the
engines are sized by the SEM output format, not by the accumulator width -
but the RUNTIME EXP does, one clock per unit. 1..31, default 20,
i.e. blocks of up to 1048576 samples out of the box.
Default: 20
Options: 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31
Number of INTEGER bits of the SEM output (the sign, when present, uses one of them).
Integer bits of the SEM output. 1..64, default 8. The standard error can never exceed $\sigma$, which can never exceed the input range, so $\text{IN}_{int}$ integer bits are always enough and usually generous. Each bit adds one clock to the square root, i.e. one clock to the tail.Default: 8
Options: 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Number of FRACTIONAL bits of the SEM output, i.e. the bits to the right of the binary point. Total width = integer + fractional bits, and must not exceed 64.
Fractional bits of the SEM output. 0..64, total width 2..64 bits, default 8 - deliberately not 0 like the rest of the family. This is the property that matters on this block: sem is $\sigma/\sqrt{N}$, so on a $2^{20}$ block it is 1024 times smaller than $\sigma$ and ten fractional bits merely get you back to one LSB of the input. Too few and the root truncates and the block faithfully reports 0. Each bit adds one clock to the tail, which at these tail lengths is cheap - be generous.Default: 8
Options: 0 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Select whether the SEM output is signed (two’s complement) or unsigned.
SIGNED or UNSIGNED SEM output. Default UNSIGNED - a standard error is never negative, and UNSIGNED buys one bit of resolution. Choose SIGNED only for a downstream bus that requires it.Default: UNSIGNED
Options: UNSIGNED SIGNED
YES: the BUSY (high from the first sample of a block until its result is out – it COVERS THE SERIAL TAIL, and its last high clock IS the OUT_DV pulse) pin is present. NO: the pin AND all of its logic are removed BEFORE synthesis, so nothing is paid for it.
YES: theBUSY pin exists. It is high from the first sample of a block
until its result is out, tail included, and its last high clock is the
OUT_DV pulse. NO: the pin and its register are removed before synthesis.
Default NO.
Default: NO
Options: NO YES
YES: the INTEGRATING (high only while the block is ACCUMULATING; it drops as soon as the N-th sample has been taken and the tail starts, so BUSY-and-not-INTEGRATING means ‘computing’) pin is present. NO: the pin AND all of its logic are removed BEFORE synthesis, so nothing is paid for it.
YES: theINTEGRATING pin exists. It is high only while the block is
accumulating, so BUSY high with INTEGRATING low means “the samples are
all in, the squarer and the root are running”. NO: the pin and its
register are removed. Default NO.
Default: NO
Options: NO YES
YES: the SAMPLE_COUNT (32 bit, how many samples have been accumulated so far in the current block: 1 after the first, N after the N-th. It is NOT cleared at the block end – it holds N until the NEXT block’s first accepted sample takes it back to 1. On a CONTINUOUS stream that happens DURING the serial tail, so at OUT_DV it reads how far into the next block the input has already got, NOT N. To capture the length of the block being presented, latch SAMPLE_COUNT on the clock INTEGRATING falls – that one always reads N) pin is present. NO: the pin AND all of its logic are removed BEFORE synthesis, so nothing is paid for it.
YES: theSAMPLE_COUNT pin exists - a fixed 32 bit count of the samples
accumulated so far in the current block, holding the final count through
the tail and past OUT_DV, so it reads the N that the error bar refers
to. NO: the pin and its counter are removed. Default NO.
Default: NO
Options: NO YES
ROUND: round to nearest when a result has to be requantised into a coarser output format. TRUNCATE: drop the bits (cheaper, adds a negative bias).
ROUND: round to nearest when the root has to be requantised into a coarser output format. TRUNCATE: drop the bits (cheaper, adds a negative bias). It applies to the final requantisation only - the digit recurrence itself always truncates below its guard bits, which is where the other half of the 1 LSB bound comes from. Default ROUND.Default: ROUND
Options: TRUNCATE ROUND
YES: clip to the largest representable value of each output format (symmetric for signed formats). NO: wrap around.
YES: clip to the largest representable value of the SEM format (symmetric bounds for signed formats). NO: wrap around. Note that the radicand loader saturates too, and for a square root that IS the output saturation: a radicand that does not fit means the root does not fit. Default YES.Default: YES
Options: NO YES
Timing: the serial tail
All post-accumulation arithmetic is serial - the block has a whole block period of slack after the N-th sample, so there is no reason to build a parallel datapath for it. The state walk is
IDLE -(block complete)-> MUL x (IN_SW + EXP) -> VAR -> LD -> SQRT x RTW -> FIN -> IDLE
OUT_DV pulses for one clock when the tail COMPLETES - not when the N-th
sample arrives - and SEM is updated on that same clock and on no other. The
latency from the N-th accepted sample to the OUT_DV pulse, counted in
clocks, is
$$ L = 2 + (\mathrm{IN_SW} + \mathrm{EXP} + 1) + (\mathrm{RTW} + 1) $$
with
$$ \mathrm{RTW} = \mathrm{SEM_{int}} + \mathrm{SEM_{fract}} + 5 $$
where $\mathrm{IN_SW}$ is the total input width, plus one bit if the input is UNSIGNED (a sample has to be promoted to signed first). Collecting terms,
$$ L = \mathrm{IN_SW} + \mathrm{SEM\ width} + \mathrm{EXP} + 9 $$
so one clock per input bit, one clock per SEM output bit, one clock per unit of EXP - and, note, nothing from Max Block Exponent: unlike Block Coefficient of Variation and Block SNR, this block’s engines are sized by the output format, not by the accumulator width, so raising Max Block Exponent costs accumulator bits but not tail clocks.
Worked numbers
For a 16 bit signed input at the default SEM format (Q8.8 unsigned,
16 bits):
- $\mathrm{RTW} = 8 + 8 + 5 = 21$
- $L = 2 + (16 + \mathrm{EXP} + 1) + (21 + 1) = 41 + \mathrm{EXP}$
- at EXP = 10 (N = 1024) that is 51 clocks, comfortably inside the block;
- the smallest exponent with $2^{\mathrm{EXP}} \ge 41+\mathrm{EXP}$ is EXP = 6, i.e. N = 64 ($64 \ge 47$; at EXP = 5, $32 < 46$).
A few more configurations:
| Input | SEM | RTW | L(EXP) | L at EXP=10 | minimum EXP |
|---|---|---|---|---|---|
| 8 bit s | Q8.8 | 21 | 33 + EXP | 43 | 6 (N = 64) |
| 16 bit s | Q8.8 | 21 | 41 + EXP | 51 | 6 (N = 64) |
| 16 bit u | Q8.8 | 21 | 42 + EXP | 52 | 6 (N = 64) |
| 16 bit s | Q8.16 | 29 | 49 + EXP | 59 | 6 (N = 64) |
| 16 bit s | Q16.16 | 37 | 57 + EXP | 67 | 6 (N = 64) |
| 32 bit s | Q16.16 | 37 | 73 + EXP | 83 | 7 (N = 128) |
A longer block gives more slack than it costs. $L$ grows by one clock per unit of EXP while $2^{\mathrm{EXP}}$ doubles, so $2^{\mathrm{EXP}} \ge L$ gets easier as EXP grows, not harder. The constraint only ever bites at the short end.
The 2^EXP >= L rule, and what happens when it is broken
The tail of one block must finish before the next block completes:
$$ 2^{\mathrm{EXP}} \ge L $$
If a block completes while the previous tail is still running, that block’s
result is DROPPED: there is no OUT_DV for it, the accumulators are
unaffected and the following blocks come out correctly, but a result is
silently skipped. There is no error pin for it.
The property page refuses a configuration whose minimum exponent exceeds
Max Block Exponent, and CompileHDL prints both numbers - the worst-case
tail length and the minimum usable EXP - in the compilation log, so the static
half of the problem is caught for you.
But EXP is a PIN. Nothing can stop a design driving it too low at RUN
TIME: an EXP of 4 or 5 that would be perfectly reasonable on Block Mean
drops every result here, with no indication other than a silent OUT_DV.
If EXP is under software control, clamp it in software to the minimum the
compiler printed.
A note on SCALE - give it fractional bits
This is the one thing to get right on this block. SEM is
$\sigma/\sqrt{N}$, so for a long block it is SMALL - that is the entire
point of the statistic:
| N | SEM relative to sigma |
|---|---|
| 64 | 1/8 |
| 1024 | 1/32 |
| 65536 | 1/256 |
| 1048576 | 1/1024 |
With IN fractional bits = 0 and a $2^{20}$ block, the standard error is
1024 times smaller than $\sigma$ - so you need ten fractional bits just
to get back to one LSB of the input, and more than that to resolve it. Ask
for too few and the root truncates and the block will faithfully report 0,
which is a perfectly correct answer to the question you asked and not the one
you wanted.
That is why the default format is Q8.8 unsigned: eight fractional bits (steps of 1/256) rather than the zero fractional bits that the rest of the family defaults to. On a long block, or on an input with several fractional bits of its own, raise it. Each output bit costs exactly one clock of tail (see the table above), which at these tail lengths is cheap.
Conversely the integer side rarely needs to be wide: SEM cannot exceed
$\sigma$, and $\sigma$ cannot exceed the input range, so
$\mathrm{SEM_{int}} \le \mathrm{IN_{int}}$ is always safe and usually
generous.
Accuracy
$\mathrm{var_num} = N!\cdot!S_2 - S_1^2$ is an exact integer: $N\cdot S_2$ is a shift (N is a power of two) and $S_1^2$ is an exact serial shift-add product. It is never two truncated quotients subtracted from each other, which is the classic way to lose all the precision in a variance.
So the only error in the answer is the square root itself: the digit recurrence truncates below $\mathrm{SQG} = 4$ guard bits and the final requantisation rounds, giving
$$ |,\mathrm{err},| \le \tfrac{2}{16} + \tfrac{1}{2} < 1\ \mathrm{LSB} $$
The host regression enforces exactly 1 LSB, never more, against a Python golden computed in exact rational arithmetic.
Note the difference from Block Crest Factor, which divides by a root and therefore compounds two errors: here the root is the answer, so the bound is absolute and does not depend on the value.
Accumulation and IN_DV
IN_DV is the only qualifier. It says “this clock carries a sample”: a
sample is added to $S_1$, squared and added to $S_2$, and counts towards N,
exactly on the clocks where IN_DV is high. Clocks with IN_DV low are
ignored completely - whatever sits on IN during them cannot corrupt the
block - while the serial tail keeps running, which is what you want: the tail
has nothing to do with the input stream.
Unconnected, IN_DV ties to '1' and EXP ties to 10 (N = 1024), so the
block free-runs with nothing wired except IN - and at N = 1024 the tail
hides comfortably for any sane format.
There is deliberately no CE pin. On the all-in-one Block Statistics block an earlier revision had one, and it did not survive synthesis: with nothing but internal state gated by it, Vitis could reason the frozen path away and delete the port from the generated entity while SciCompiler’s wrapper still wired it, which failed a real Vivado build with [VRFC 10-718] formal port <ce> does not exist in entity. The whole per-operator family was built without one. To stall this block, gate its
IN_DV- and note that there would be no reason to stall the tail anyway.
When EXP changes
EXP is clamped to Max Block Exponent and then latched on the first
accepted sample of a block, and held for that whole block. A change
therefore takes effect on the NEXT block: a block in progress always
finishes against the N it was started with, and a block is never emitted
against a different N than the one it was accumulated with.
That matters more here than almost anywhere else, because the latched
exponent appears three times over in the radicand shift ($3,\mathrm{EXP}$)
and once more in the length of the serial squarer. Sweeping EXP from a
register interface while the stream runs is safe, and every result stays
self-consistent with the N it was measured over - which is exactly what you
need when you are sweeping N to see whether averaging longer still helps.
Latch SAMPLE_COUNT alongside the result if you want that N recorded.
Knowing where the block is: BUSY, INTEGRATING and SAMPLE_COUNT
Three optional status outputs, all defaulting to NO. They answer different questions, and on this block the difference is useful because the tail is long:
INTEGRATING |
BUSY |
|
|---|---|---|
| accumulating the block | 1 | 1 |
| serial tail computing | 0 | 1 |
| idle | 0 | 0 |
Every output of this block is a register, so each status bit is observed on the clock after the event that sets it:
INTEGRATINGrises on the clock after the FIRST sample of a block is accepted and falls on the clock after the N-th - it is high exactly while the block is ACCUMULATING.BUSYhigh withINTEGRATINGlow is precisely the square-then-root tail.BUSYcovers the accumulation and the tail. It rises withINTEGRATING, stays high across the tail, and its LAST HIGH CLOCK IS THEOUT_DVPULSE; it falls on the clock after.- On a continuous stream the next block starts before the previous tail
ends, so
BUSYnever drops andINTEGRATINGdips for exactly one clock per block boundary - which makes it a free block marker. SAMPLE_COUNTis a fixed 32 bits and reads 1 after the first accepted sample, N after the N-th. It is NOT cleared at the block end: it HOLDS N through the tail and pastOUT_DV, until the first sample of the next block takes it back to 1. so it reads N atOUT_DVonly when the input STOPS for the whole tail; on a CONTINUOUS stream the next block has already started andOUT_DVshows how far into it you are. The clock that always reads N is the oneINTEGRATINGfalls on - which is the useful thing to latch alongside the result (the N that the error bar refers to), and also the cheapest way to confirm at run time that the block was long enough for the tail. OnlyRESETclears it to 0.
Q formats
Both ports carry their own fixed point format (integer bits, fractional bits,
sign), the same convention as the Fixed P. family. The root is requantised
into the SEM format with the selected rounding (nearest / truncate) and
overflow policy (saturate / wrap); saturation is symmetric for signed formats,
as everywhere else in the toolchain.
Sizing hints:
- fractional bits are the whole game - see “A note on SCALE”;
SEMis never negative, so UNSIGNED buys one bit and is the default;- $\mathrm{SEM_{int}} \le \mathrm{IN_{int}}$ is always enough for range, since the standard error cannot exceed $\sigma$ and $\sigma$ cannot exceed the input range;
- every bit of
SEM, integer or fractional, adds exactly one clock to the tail.
Verification
The core is regression tested by a host-side csim harness
(tb/block-ops/run_tb.ps1) that runs one simulated clock at a time and
follows OUT_DV. The expected values come from tb/block-ops/gen_golden.py,
which evaluates $\sigma/\sqrt{N}$ in exact rational arithmetic and shares no
algorithm with the core; the tolerance is exactly 1 LSB, never more.
Coverage includes pseudo-random and ramp inputs, a constant block
(sem = 0), maximum positive and maximum negative samples, unsigned input,
fractional input and output formats, odd exponents (which is what pins the
claim that the $3,\mathrm{EXP}$ shift needs no $\sqrt{2}$ approximation),
truncate instead of round, IN_DV gaps inside the accumulation, an EXP that
changes half way through a block, and an EXP driven above Max Block
Exponent to exercise the clamp. The tail length is checked against the
formula at compile time: three copies of it exist - the BSE_TAIL macro
in the core, tail_len() in the generator and TailClocks() in the plugin -
and the testbench refuses to build if they disagree. The status outputs are
checked clock by clock against the contract above.