
Float SUM TM
Time-multiplexed floating-point addition operator based on Xilinx Floating Point IP. Supports single (32-bit) and double (64-bit) precision, configurable DSP usage, optional TM mode for second operand, and multiple TM phases (1-32) for high-throughput parallel computation in arithmetic processing pipelines.
Introduction
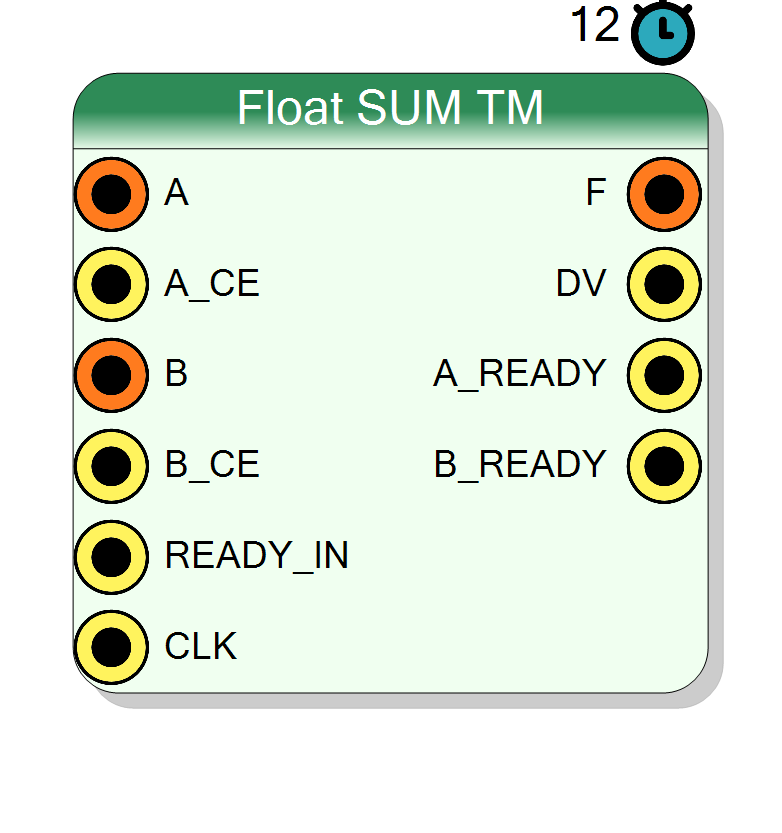
This block performs IEEE 754 floating-point addition using the Xilinx Floating Point IP core. The component supports Time Multiplexing (TM): multiple parallel computation units (phases) share the same clock cycle, enabling high sample rates with predictable latency.
On every rising edge of CLK, if A_CE = 1, B_CE = 1, and READY_IN = 1, the operator performs
$$ \mathrm{F}(n) = \mathrm{A}(n) + \mathrm{B}(n), $$
where all operands are IEEE 754 floating-point values. The TM Factor property determines how many parallel instances are instantiated.
Pin Description
Floating-point input A, always TM.
Width: (Exponent + Mantissa) × TMFactor
- Single: 32 bits/phase → total 32×TMFactor
- Double: 64 bits/phase → total 64×TMFactor IEEE 754 format first operand for addition.
A_CE = 0 the A input is not accepted.
Maps to s_axis_a_tvalid in the AXI Stream interface.
Floating-point input B.
- If B is TM = YES: TM bus of width same as A
- If B is TM = NO: Scalar of single phase width (replicated to all phases) IEEE 754 format second operand for addition.
B_CE = 0 the B input is not accepted.
Maps to s_axis_b_tvalid in the AXI Stream interface.
m_axis_result_tready. Default: ‘1’ if not connected.
m_axis_result_tvalid signals.
s_axis_a_tready signals.
s_axis_b_tready signals.
Properties
Time Multiplexing factor (number of phases)
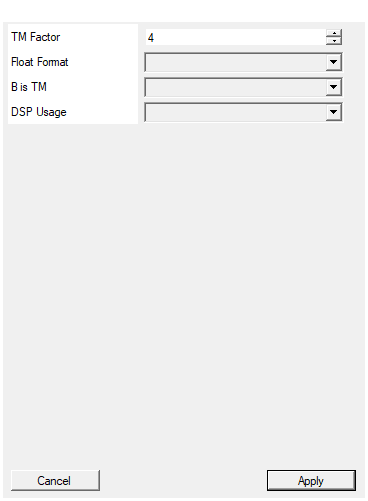
Number of time-multiplexed phases (parallel computation units). Range: 1 – 32. Higher values increase throughput proportionally but consume more FPGA resources (N instances of the Xilinx IP).Default: 4
Range: 1 – 32
Select between single precision 32 bit and double precision 64 bit
Floating-point format for all inputs and output:
Single→ IEEE 754 single precision (32-bit): 8 exp + 24 mantissaDouble→ IEEE 754 double precision (64-bit): 11 exp + 53 mantissa
Determines precision and range of the computation.
Default: Single
Options: Single Double
Select if input B is Time Multiplexed or the same for all phases
Selects input B mode:
YES→ Input B is a TM bus; each phase gets its sliceNO→ Input B is scalar; replicated to all phases
Use NO for adding a constant to all TM channels.
Default: YES
Options: NO YES
DSP Usage. Single precision: No [0], Full[2]. Double precision: No[0], Full[3]
DSP slice usage mode:
No_Usage→ Minimize DSP usage (more LUTs)Full_Usage→ Maximize DSP usage (fewer LUTs)
Single precision DSP count: No [0], Full[2] Double precision DSP count: No[0], Full[3]
Default: Full_Usage
Options: No_Usage Full_Usage
Functional description
The component wraps the Xilinx Floating Point IP (operation type: Add)
and replicates it N times (where N = TM Factor) to support time-multiplexed
data streams.
Input modes
- Input A is always TM, with width
(Exponent + Mantissa) × TMFactor - Input B can be either:
- TM mode (B is TM = YES): Same width as A, each phase gets its slice
- Broadcast mode (B is TM = NO): Single value replicated to all phases
Output
- Output
Fis always TM, with the same width as input A
Data valid and ready handshake
A_CE(input): Input A clock enableB_CE(input): Input B clock enableDV(output): Output data valid, asserted when all phases have valid outputA_READY(output): Ready to accept new input A (AND of all phase ready signals)B_READY(output): Ready to accept new input B (AND of all phase ready signals)READY_IN(input): Downstream ready signal
Mathematical background
IEEE 754 floating-point addition with proper rounding and special case handling:
$$ x + y = \text{round}(x + y) $$
Special cases:
- $x + 0 = x$
- $\infty + x = \infty$ (for finite $x$)
- $\infty + \infty = \infty$
- $\infty + (-\infty) = \text{NaN}$
- $\text{NaN} + x = \text{NaN}$
Timing
The Xilinx Floating Point IP has a fixed latency of 12 clock cycles per phase:
| Property | Latency (clock cycles) |
|---|---|
| Addition | 12 |
Total system delay: T_delay = 12 × T_CLK.
In TM mode, all phases operate in parallel with the same latency, producing
TMFactor outputs per cycle after the initial pipeline fill.
DSP Usage
Addition can be implemented with different DSP slice usage:
- Single precision: No [0], Full[2]
- Double precision: No[0], Full[3]
Higher DSP usage typically provides better performance but consumes more FPGA resources.
Typical use cases
- Accumulation in DSP algorithms
- Vector addition
- Signal combination and mixing
- Offset correction
- FIR filter implementation
Waveform example
Example with TM Factor = 4, Single precision, B is TM = YES.
Note: 12 clock cycles of latency from input to output.