
DSP - BLOCK SLOPE STATS
The MEAN and the STANDARD DEVIATION of the FIRST DIFFERENCE d[i] = x[i] - x[i-1] over a block of N consecutive samples. The first difference is a one-tap high pass: it deletes any constant offset and keeps only how fast the signal is moving. SLOPE_MEAN is therefore the average RAMP RATE of the block - drift, a leaking baseline, a detector warming up - and is EXACTLY zero for any block that starts and ends at the same value. SLOPE_SIGMA is the sample-to-sample ROUGHNESS and, unlike Block Std Dev, does not see slow wander at all, which makes it the better noise estimator on a DRIFTING signal; for white noise of standard deviation s it converges to s*sqrt(2). N is a power of two chosen at RUN TIME on the EXP input pin (EXP = 10 means N = 1024), so every division by N is an exact arithmetic shift. THE FIRST DIFFERENCE CROSSES THE BLOCK BOUNDARY ON PURPOSE - d[0] is x[0] minus the last accepted sample of the PREVIOUS block - so that there are exactly N differences; the consequence is that after RESET the held sample is 0 and the FIRST block is contaminated by x[0], so DISCARD THE FIRST BLOCK. SLOPE_MEAN is BIT EXACT and needs no serial arithmetic at all; SLOPE_SIGMA is within 1 LSB and adds a serial square and a serial square root. IN_DV is the only qualifier and there is deliberately no CE pin. Optional BUSY / INTEGRATING / SAMPLE_COUNT status outputs.
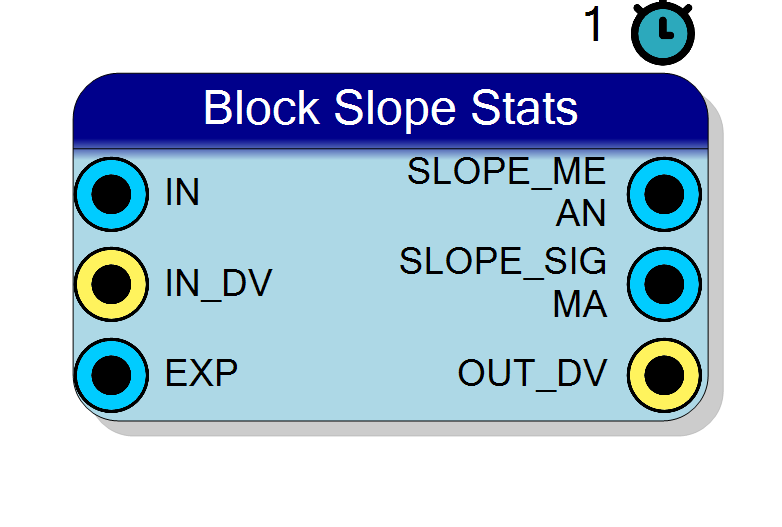
Introduction
The Block Slope Stats block chops the input stream into consecutive blocks of N samples, forms the first difference
$$ d_i = x_i - x_{i-1} $$
and, at the end of each block, publishes the mean and the standard deviation of those N differences:
$$ \mathrm{SLOPE_MEAN} = \frac{1}{N}\sum_{i=0}^{N-1} d_i , \qquad \mathrm{SLOPE_SIGMA} = \sqrt{\ \overline{d^2} - \bar{d}^{,2}\ } $$
N is a runtime input, not a property. You drive the exponent on the
EXP pin and the block size is $N = 2^{\mathrm{EXP}}$:
| EXP | N | EXP | N |
|---|---|---|---|
| 4 | 16 | 12 | 4096 |
| 6 | 64 | 16 | 65536 |
| 8 | 256 | 20 | 1048576 |
Because N is a power of two, every division by N is an exact arithmetic shift. There is no divider and no reciprocal ROM anywhere in the block - which is also why the block size can be changed while the design is running, for free.
What each output is FOR
The first difference is a one-tap high-pass filter: it deletes any constant offset and keeps only how fast the signal is moving. The two outputs then answer two different questions.
SLOPE_MEAN is the average RAMP RATE of the block, in input LSBs per
sample. It measures drift: a leaking baseline, a charging coupling
capacitor, a detector warming up, a slow control loop that has not settled.
The sum of the differences telescopes, so
$$ \sum_{i=0}^{N-1} d_i = x_{N-1} - x_{-1} \quad\Longrightarrow\quad \mathrm{SLOPE_MEAN} = \frac{\text{net change across the block}}{N} $$
where $x_{-1}$ is the last accepted sample of the previous block. Two useful consequences: it is EXACTLY zero for any block that starts and ends at the same value, whatever the signal did in between; and it depends only on the two endpoints, so it is a drift meter, not a shape meter.
SLOPE_SIGMA is the sample-to-sample ROUGHNESS. Because the difference
has already removed everything constant, and heavily attenuated everything
slow, it does not see drift at all. That is exactly what makes it the
better noise estimator on a signal that is moving: Block Std Dev on a
drifting baseline reports the drift, not the noise, while this reports the
noise. For white noise of standard deviation $s$ the differences are the
difference of two independent samples, so
$$ \mathrm{SLOPE_SIGMA} \longrightarrow s\sqrt{2} \approx 1.414,s $$
To recover $s$, multiply by $1/\sqrt{2} \approx 0.7071$. On a signal whose noise is correlated sample to sample - anything that has been through a filter
- the factor is smaller than $\sqrt{2}$, so calibrate it once against a known source rather than assuming it.
Together they are a cheap signal quality monitor: SLOPE_MEAN says how
fast the channel is walking away, SLOPE_SIGMA says how noisy it is, and they
are independent of each other.
Cost
SLOPE_MEAN alone is one subtractor, one accumulator, one barrel shifter
and one requantiser - no multiplier, no divider and no serial arithmetic
at all, so its result is out 2 clocks after the block’s last sample.
SLOPE_SIGMA adds a squarer during accumulation (the only multiplier in
the block), a second accumulator, and a serial tail: one reused shift-add
stage for $S_d \cdot S_d$ and one reused digit-recurrence square root stage.
The cost is CLOCKS, not DSPs - there is no multiplier in the tail at all.
When to use this instead of Block Statistics
The all-in-one Block Statistics block is not deprecated, but note first: it has no slope statistics. It computes the moments of the SAMPLES, not of their differences, so there is no output there that corresponds to either of these. The usual family rule therefore applies with one extra clause:
- you want several statistics of the SAME block - the mean and the RMS and the min/max of the same N samples - use Block Statistics. They share one accumulator and one serial tail, so the second and third statistic are nearly free.
- you want exactly one number - use this block, or its per-operator sibling. Then you synthesise only that number: the pin list, the logic and the tail are all that it needs, and nothing else reaches the synthesiser.
- you want these numbers - use this block, because there is nowhere else to get them. Pair it with a Block Statistics block on the same stream if you also want the moments of the samples themselves.
Two Block Statistics blocks side by side would duplicate the accumulators; two per-operator blocks side by side duplicate them too. One Block Statistics block never does.
Pin Description
IN_DV is high.
'1'. (There is deliberately no CE pin - to stall the block, gate this.)
SLOPE_SIGMA enabled it also lengthens the tail
by one clock per unit - keep it at or above the minimum usable exponent
the compilation log prints. Unconnected defaults to 10 (N = 1024).
OUT_DV clock and on no other; it holds
the previous block’s result until then. Present on the symbol only when
Enable SLOPE_MEAN = YES.
The standard deviation of the N differences, in the SLOPE_SIGMA Q format
- the sample-to-sample roughness. It does not see slow drift at all,
which makes it the better noise estimator on a moving signal; for white
noise of standard deviation $s$ it converges to $s\sqrt{2}$, so multiply
by 0.7071 to recover $s$. Accurate to within 1 LSB (the square root is the
only approximation). Enabling it adds the serial tail - see “Timing” - and
every extra bit of width costs one more clock. Updated on the
OUT_DVclock and on no other. Present on the symbol only when Enable SLOPE_SIGMA = YES.
SLOPE_SIGMA off,
and 2 + (DW + EXP + 1) + (RTW + 1) with it on. Both enabled outputs are
updated on this clock and on no other. BUSY is still high here and falls
on the next clock. The first pulse after a reset should be ignored -
see “The first difference crosses the block boundary”.
OUT_DV pulse, and it falls on the clock after. On a continuous stream it
simply stays high. Present on the symbol only when Enable BUSY = YES.
BUSY high with this low is the serial tail, which on this block is
tens of clocks long. On a continuous stream it dips for exactly one clock
per block boundary, which makes it a free block marker. Present on the
symbol only when Enable INTEGRATING = YES.
How many samples have been accumulated so far in the current block: 1 after the first, N after the N-th. It is NOT cleared at the end of a block
- it HOLDS the final count through the whole tail and past
OUT_DV, until the first sample of the next block takes it back to 1, it reads N atOUT_DVonly when the input STOPS for the whole tail. On a CONTINUOUS stream the next block has already started by then, soOUT_DVshows how far into it the input has got, not N - the clock that always reads N is the oneINTEGRATINGfalls on. OnlyRESETclears it to 0. Fixed 32 bits. Present on the symbol only when Enable SAMPLE_COUNT = YES.
Properties
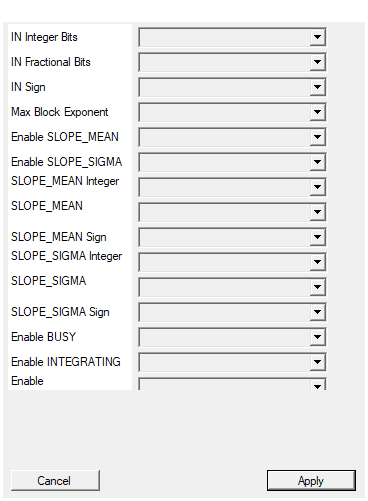
Number of INTEGER bits of the input sample (the sign, when present, uses one of them).
Integer bits of the input sample (the sign, when present, uses one of them). 1..64. Default 16.Default: 16
Options: 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Number of FRACTIONAL bits of the input sample, i.e. the bits to the right of the binary point. Total width = integer + fractional bits, and must not exceed 64.
Fractional bits of the input sample. 0..64. Total input width must be 2..64 bits. Default 0.Default: 0
Options: 0 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Select whether the input sample is signed (two’s complement) or unsigned.
SIGNED (two’s complement) or UNSIGNED input. Default SIGNED. An UNSIGNED input costs one extra bit internally, because a sample has to be promoted to signed before a difference can be formed - and, withSLOPE_SIGMA
enabled, one extra clock of tail, because DW = IN_SW + 1 appears in the
latency formula.
Default: SIGNED
Options: UNSIGNED SIGNED
Largest block-size exponent the accumulators are sized for: the block can be up to 2^MaxBlockExponent samples long. The EXP input is clamped to this value at run time. Raising it widens the internal accumulators, and ON THE BLOCKS WHOSE SERIAL ENGINES ARE SIZED FROM THOSE ACCUMULATORS (Coefficient of Variation, SNR, Skewness, Kurtosis, Correlation, Autocorrelation, Linear Regression) it also LENGTHENS THE SERIAL TAIL – even when the runtime EXP is small. Keep it at the largest block you actually use. The default of 20 covers blocks of up to 1048576 samples.
Largest block-size exponent the accumulators are sized for: the block can be up to $2^{\text{MaxBlockExponent}}$ samples long, and theEXP input is
clamped to this value at run time. Raising it widens both difference
accumulators by one bit per unit and raises the worst case tail by one
clock per unit (the tail grows with the RUNTIME exponent; this property
bounds it, and is the value the compilation log quotes). Keep it at the
largest block you actually use. 1..31, default 20, i.e. blocks of up
to 1048576 samples out of the box.
Default: 20
Options: 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31
YES: the the SLOPE_MEAN output pin is present. NO: the pin AND all of its logic are removed BEFORE synthesis, so nothing is paid for it.
YES: theSLOPE_MEAN pin exists - the average ramp rate of the block. It
needs no serial arithmetic at all: on its own the tail is a constant 2
clocks. NO: the pin, its accumulator, its shifter and its requantiser are
removed before synthesis. Default YES.
Default: YES
Options: NO YES
YES: the the SLOPE_SIGMA output pin is present. NO: the pin AND all of its logic are removed BEFORE synthesis, so nothing is paid for it.
YES: theSLOPE_SIGMA pin exists - the standard deviation of the
differences. This is the expensive one: it adds a squarer during
accumulation, a second accumulator, a serial shift-add multiplier and a
serial square root, and it turns L from a constant 2 into
2 + (DW + EXP + 1) + (RTW + 1). NO: all of that is removed. Default YES.
Default: YES
Options: NO YES
Number of INTEGER bits of the SLOPE_MEAN output (the sign, when present, uses one of them).
Integer bits of the SLOPE_MEAN output. 1..64, default 16. The slope mean is a net change divided by N, so it can never leave the range of a sample and the input integer bits are always enough.Default: 16
Options: 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Number of FRACTIONAL bits of the SLOPE_MEAN output, i.e. the bits to the right of the binary point. Total width = integer + fractional bits, and must not exceed 64.
Fractional bits of the SLOPE_MEAN output. 0..64, total width 2..64 bits, default 0 - and 0 is usually the wrong choice here. A drift of 1 LSB across a 1024-sample block is a slope of $2^{-10}$ and reads as zero in an integer format. Give it at least as many fractional bits as the largestEXP you drive; the accumulator carries them exactly.
Default: 0
Options: 0 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Select whether the SLOPE_MEAN output is signed (two’s complement) or unsigned.
SIGNED or UNSIGNED SLOPE_MEAN output. Default SIGNED, and it should stay SIGNED unless the signal can only ever rise - a falling ramp has a negative slope, and an UNSIGNED format would saturate every one of them to 0.Default: SIGNED
Options: UNSIGNED SIGNED
Number of INTEGER bits of the SLOPE_SIGMA output (the sign, when present, uses one of them).
Integer bits of the SLOPE_SIGMA output. 1..64, default 16. It is bounded by the width of one difference, so the input integer bits plus one are always enough. Every bit here costs one clock of serial tail (RTW = width + 5).Default: 16
Options: 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Number of FRACTIONAL bits of the SLOPE_SIGMA output, i.e. the bits to the right of the binary point. Total width = integer + fractional bits, and must not exceed 64.
Fractional bits of the SLOPE_SIGMA output. 0..64, total width 2..64 bits, default 0. Useful when the noise is small compared with an LSB of the input scale. Every bit here also costs one clock of serial tail.Default: 0
Options: 0 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64
Select whether the SLOPE_SIGMA output is signed (two’s complement) or unsigned.
SIGNED or UNSIGNED SLOPE_SIGMA output. Default UNSIGNED - a standard deviation is never negative, and UNSIGNED buys one bit of range for free.Default: UNSIGNED
Options: UNSIGNED SIGNED
YES: the BUSY (high from the first sample of a block until its result is out – it COVERS THE SERIAL TAIL, and its last high clock IS the OUT_DV pulse) pin is present. NO: the pin AND all of its logic are removed BEFORE synthesis, so nothing is paid for it.
YES: theBUSY pin exists. It is high from the first sample of a block
until its result is out, tail included, and its last high clock is the
OUT_DV pulse. NO: the pin and its register are removed before synthesis.
Default NO.
Default: NO
Options: NO YES
YES: the INTEGRATING (high only while the block is ACCUMULATING; it drops as soon as the N-th sample has been taken and the tail starts, so BUSY-and-not-INTEGRATING means ‘computing’) pin is present. NO: the pin AND all of its logic are removed BEFORE synthesis, so nothing is paid for it.
YES: theINTEGRATING pin exists. It is high only while the block is
accumulating, so BUSY high with INTEGRATING low means “the samples are
all in, I am computing” - a long, visible state on this block. NO: the pin
and its register are removed. Default NO.
Default: NO
Options: NO YES
YES: the SAMPLE_COUNT (32 bit, how many samples have been accumulated so far in the current block: 1 after the first, N after the N-th. It is NOT cleared at the block end – it holds N until the NEXT block’s first accepted sample takes it back to 1. On a CONTINUOUS stream that happens DURING the serial tail, so at OUT_DV it reads how far into the next block the input has already got, NOT N. To capture the length of the block being presented, latch SAMPLE_COUNT on the clock INTEGRATING falls – that one always reads N) pin is present. NO: the pin AND all of its logic are removed BEFORE synthesis, so nothing is paid for it.
YES: theSAMPLE_COUNT pin exists - a fixed 32 bit count of the samples
accumulated so far in the current block, holding the final count through
the tail and past OUT_DV. NO: the pin and its counter are removed.
Default NO.
Default: NO
Options: NO YES
ROUND: round to nearest when a result has to be requantised into a coarser output format. TRUNCATE: drop the bits (cheaper, adds a negative bias).
ROUND: round to nearest when a result has to be requantised into a coarser output format. TRUNCATE: drop the bits (cheaper, adds a negative bias). Applies to both outputs. Default ROUND.Default: ROUND
Options: TRUNCATE ROUND
YES: clip to the largest representable value of each output format (symmetric for signed formats). NO: wrap around.
YES: clip to the largest representable value of each output format (symmetric bounds for signed formats). NO: wrap around. It matters most onSLOPE_MEAN with an UNSIGNED format, where every falling ramp would
otherwise wrap. Default YES.
Default: YES
Options: NO YES
THE FIRST DIFFERENCE CROSSES THE BLOCK BOUNDARY
$d_0$ of a block is $x_0$ minus the LAST ACCEPTED SAMPLE OF THE PREVIOUS BLOCK, not $x_1 - x_0$. This is deliberate, and there are two reasons - the first one is the important one:
- It gives EXACTLY N differences per block, so “divide by N” stays a SHIFT. The N-1 differences that live strictly inside a block would need a real division by a non-power-of-two: a divider, a longer tail and a rounding error, for a definition that is no better.
- The stream is continuous. The step between two consecutive samples is a real step whether or not a block boundary happens to sit between them.
This is the same reasoning that makes Block Zero Crossings carry its sign memory across blocks, and Block Peak Count its Schmitt state.
CONSEQUENCE: DISCARD THE FIRST BLOCK
After
RESETthe held “previous sample” is 0. So the first difference of the first block is $x_0 - 0 = x_0$ itself - the whole sample, not a step - and both statistics of that block are contaminated by it. On a signal sitting at a baseline of 1000 LSB, the first block’sSLOPE_MEANis high by $1000/N$ and itsSLOPE_SIGMAis dominated by that one enormous “difference”.Discard the first block after every reset, or arrange to reset while the input is at zero.
OUT_DVcounts the blocks for you; ignore the first pulse.
“Previous sample” means previous ACCEPTED sample
Clocks with IN_DV low do not exist as far as this core is concerned. The
held sample is updated only on accepted samples, so a gapped stream
differences the samples it was actually given, not the gaps: if samples
arrive at clocks 4, 9 and 11, the differences are $x_9 - x_4$ and
$x_{11} - x_9$.
That is the right behaviour for a decimated or gated stream, but be aware of
what it means physically: the difference is per SAMPLE, not per CLOCK. If
your IN_DV gaps are irregular, SLOPE_MEAN is a rate per sample and not a
rate per unit time.
Exactness
Both statistics are built the way Block Mean and Block Std Dev build theirs, on the difference stream instead of the sample stream. With $S_d = \sum d_i$ and $S_{dd} = \sum d_i^2$:
$$ \mathrm{SLOPE_MEAN} = \frac{S_d}{N}, \qquad \mathrm{var}{\mathrm{num}} = N,S{dd} - S_d^2, \qquad \mathrm{SLOPE_SIGMA} = \frac{\sqrt{\mathrm{var}_{\mathrm{num}}}}{N} $$
$N S_{dd}$ is a shift and $S_d \cdot S_d$ is an exact serial shift-add product, so $\mathrm{var}_{\mathrm{num}}$ is an exact integer. Therefore:
SLOPE_MEANis BIT EXACT - the only error is the single final requantisation into the Q format you chose;SLOPE_SIGMAis within 1 LSB - the square root is the only approximation anywhere in the block, and it is computed with 4 guard bits below the output LSB so that the final rounding still has something to round.
The variance numerator is clamped non-negative before the root, so no configuration can present a radicand the root engine cannot take.
That is not an aspiration. The host regression (tb/block-ops/run_tb.ps1)
demands tolerance ZERO on the mean against a Python golden
(tb/block-ops/gen_golden.py) that evaluates the definitions above in exact
rational arithmetic and shares no algorithm with the core.
Note also what the difference does to the dynamic range: one difference is one bit wider than a promoted sample (call it DW = IN_SW + 1), because the difference of two full-scale samples of opposite sign needs it. The two accumulators are sized from that, and nothing in the datapath can overflow.
Accumulation and IN_DV
IN_DV is the only qualifier. It says “this clock carries a sample”: a
difference is formed, accumulated, and counts towards N, exactly on the clocks
where IN_DV is high. Clocks with IN_DV low are ignored completely -
whatever sits on IN during them cannot corrupt the block or move the held
sample - while the tail keeps running, which is what you want: the tail has
nothing to do with the input stream.
Unconnected, IN_DV ties to '1' and EXP ties to 10 (N = 1024), so the
block free-runs with nothing wired except IN.
There is deliberately no CE pin. On the all-in-one Block Statistics block an earlier revision had one, and it did not survive synthesis: with nothing but internal state gated by it, Vitis could reason the frozen path away and delete the port from the generated entity while SciCompiler’s wrapper still wired it, which failed a real Vivado build with [VRFC 10-718] formal port <ce> does not exist in entity. The whole per-operator family was built without one. To stall this block, gate its
IN_DV- a block that only accumulates onIN_DVhas no need to be frozen.
When EXP changes
EXP is clamped to Max Block Exponent and then latched on the first
accepted sample of a block, and held for that whole block. A change
therefore takes effect on the NEXT block: a block in progress always
finishes against the N it was started with, and a block is never emitted
against a different N than the one it was accumulated with. You can sweep
EXP from a register interface while the stream runs and every result stays
self-consistent.
Note that with SLOPE_SIGMA enabled the tail length depends on EXP -
see below.
Timing: the serial tail
Why it is serial
A block has a whole block period of slack after its N-th sample: the next
result is not due for another $2^{\mathrm{EXP}}$ clocks. So there is no reason
to build a parallel datapath for the post-accumulation arithmetic. II=1 is
only needed while ACCUMULATING - one subtract, one square, two adds per
sample - and the tail has all the time in the world:
- $S_d \cdot S_d$ is ONE reused shift-add stage stepped once per clock, consuming one bit of $|S_d|$ per clock, $\mathrm{DW} + \mathrm{EXP}$ steps;
- the square root is ONE reused compare-subtract stage stepped once per clock, producing one result bit per clock, $\mathrm{RTW}$ steps.
The latency contract
OUT_DV pulses for one clock when the tail COMPLETES, L clocks after the
clock on which the N-th sample of the block was accepted - not when that
sample arrives. Both outputs are updated on that same clock and on no other.
With SLOPE_SIGMA OFF the state walk is IDLE -(go)-> FIN -> IDLE and
$$ L = 2 $$
a constant, exactly like Block Mean.
With SLOPE_SIGMA ON the walk is
IDLE -(go)-> MUL x (DW + EXP) -> VAR -> LD -> SQRT x RTW -> FIN -> IDLE,
and with OUT_DV registered
$$ \mathrm{DW} = \mathrm{IN_SW} + 1, \qquad \mathrm{RTW} = \mathrm{SLOPE_SIGMA\ width} + \mathrm{SQG} + 1 = \mathrm{SLOPE_SIGMA\ width} + 5 $$
$$ L = 2 + (\mathrm{DW} + \mathrm{EXP} + 1) + (\mathrm{RTW} + 1) $$
where $\mathrm{IN_SW}$ is the signed working width of a sample: the input width, +1 if the input is UNSIGNED (a sample has to be promoted to signed before it can be differenced). Both terms are user visible: a WIDE SLOPE_SIGMA format costs root steps and a LONG BLOCK costs multiply steps.
Like Block Std Dev and Block Variance, this block’s latency depends on the runtime exponent. A longer block makes $|S_d|$ wider and therefore costs more multiply steps. But a longer block also gives more slack: the block grows exponentially in EXP and the tail only linearly, so the $2^{\mathrm{EXP}} \ge L$ constraint gets easier as EXP grows, not harder.
The 2^EXP >= L rule
The tail of one block must finish before the next block completes:
$$ 2^{\mathrm{EXP}} \ge L $$
If a block completes while the previous tail is still running, that block’s
result is DROPPED. A completed block is only handed to the tail when the
tail is IDLE, so: no OUT_DV for it, the accumulators are unaffected, later
blocks come out correctly - and there is no overrun pin. A result is simply
skipped.
Three things guard against it, and one hole remains:
- the property validator refuses a configuration whose minimum exponent exceeds Max Block Exponent, and tells you the tail length and the minimum;
CompileHDLprints the tail length and the minimum usable EXP into the compilation log for every placement;- but
EXPis a PIN. Nothing can stop a user driving it below the minimum at RUN TIME. If you makeEXPruntime programmable from a register interface, clamp it in your own logic - the block will not complain, it will just stop emitting some results.
Worked numbers
| Input | SLOPE_SIGMA | DW | RTW | L | minimum EXP |
|---|---|---|---|---|---|
| any | disabled | - | - | 2 | 1 (N = 2) |
| 8 bit signed | 16 bit (default) | 9 | 21 | 34 + EXP | 6 (N = 64) |
| 8 bit signed | 8 bit | 9 | 13 | 26 + EXP | 5 (N = 32) |
| 16 bit signed | 16 bit (default) | 17 | 21 | 42 + EXP | 6 (N = 64) |
| 16 bit signed | 32 bit | 17 | 37 | 58 + EXP | 6 (N = 64) |
| 16 bit unsigned | 16 bit (default) | 18 | 21 | 43 + EXP | 6 (N = 64) |
Take the fourth row - the default configuration - in full. A 16 bit
signed input gives $\mathrm{IN_SW} = 16$ and $\mathrm{DW} = 17$; the
default SLOPE_SIGMA format (16 integer bits, 0 fractional bits, unsigned)
gives $\mathrm{RTW} = 16 + 5 = 21$. So
$$ L = 2 + (17 + \mathrm{EXP} + 1) + (21 + 1) = 42 + \mathrm{EXP} $$
At $\mathrm{EXP} = 5$ that is $L = 47$ and $2^5 = 32 < 47$, so it does not fit; at $\mathrm{EXP} = 6$ it is $L = 48$ and $2^6 = 64 \ge 48$, so it does. The minimum usable EXP is 6, a block of 64 samples - and every larger exponent fits too. With the default $\mathrm{EXP} = 10$ the tail is 52 clocks inside a 1024-sample block: still over 94% idle.
Turning SLOPE_SIGMA off collapses all of this: L drops to a constant 2
and the minimum usable exponent to 1. If all you want is the drift, that is a
much cheaper block.
Knowing where the block is: BUSY, INTEGRATING and SAMPLE_COUNT
Three optional status outputs, all defaulting to NO. They answer different questions:
INTEGRATING |
BUSY |
|
|---|---|---|
| accumulating the block | 1 | 1 |
| tail computing | 0 | 1 |
| idle | 0 | 0 |
Every output of this block is a register, so each status bit is observed on the clock after the event that sets it:
INTEGRATINGrises on the clock after the FIRST sample of a block is accepted and falls on the clock after the N-th - it is high exactly while the block is ACCUMULATING.BUSYcovers the accumulation and the tail. It rises withINTEGRATING, stays high across the tail, and its LAST HIGH CLOCK IS THEOUT_DVPULSE; it falls on the clock after. SoBUSYhigh withINTEGRATINGlow means “the samples are all in, I am computing” - which on this block is a visible state, tens of clocks long.- On a continuous stream the next block starts before the previous tail
ends, so
BUSYnever drops andINTEGRATINGdips for exactly one clock per block boundary - which makes it a free block marker. SAMPLE_COUNTis a fixed 32 bits and reads 1 after the first accepted sample, N after the N-th. It is NOT cleared at the block end: it HOLDS N through the whole tail and pastOUT_DV, until the first sample of the next block takes it back to 1. so it reads N atOUT_DVonly when the input STOPS for the whole tail; on a CONTINUOUS stream the next block has already started andOUT_DVshows how far into it you are. The clock that always reads N is the oneINTEGRATINGfalls on - which is the useful thing to latch alongside the results. OnlyRESETclears it to 0.
Q formats
All three data ports carry their own fixed point format (integer bits, fractional bits, sign), the same convention as the Fixed P. family. Each result is requantised into its own format with the selected rounding (nearest / truncate) and overflow policy (saturate / wrap); saturation is symmetric for signed formats, as everywhere else in the toolchain.
Sizing rules:
SLOPE_MEANmust be SIGNED for any signal that can fall as well as rise - a falling ramp has a negative slope. That is the default. Its magnitude can never exceed one sample’s worth of range (it is a net change divided by N), so the input’s integer bits are always enough; the fractional bits are where the value actually lives. A drift of 1 LSB over a 1024-sample block is a slope of $2^{-10}$, which reads as 0 in the default Q16.0 format. GiveSLOPE_MEANat least as many fractional bits as the largestEXPyou drive, or slow drift is invisible.SLOPE_SIGMAis UNSIGNED by default - a standard deviation is never negative, and UNSIGNED buys one bit. It is at most the full difference range, so DW bits of integer always fit. Remember that every extra bit ofSLOPE_SIGMAwidth costs one clock of tail.
Enabling and disabling outputs
Each of the two data outputs has its own enable, both defaulting to YES.
Turning one off removes the pin and all of its logic before synthesis (the
enables are preprocessor switches on the HLS core, so nothing reaches the
synthesiser at all). Disabling SLOPE_SIGMA removes the squarer, the second
accumulator, the serial multiplier and the whole square root engine, and
shortens L to 2. At least one output must be enabled - the property page
refuses a configuration with both off, because the block would have nothing to
say.
Verification
The core is regression tested by a host-side csim harness
(tb/block-ops/run_tb.ps1) that runs one simulated clock at a time and
follows OUT_DV. The expected values come from tb/block-ops/gen_golden.py,
which evaluates the definitions above in exact rational arithmetic and shares
no algorithm with the core. Slope coverage includes pseudo-random input
(SL_RAND_E6), a pure ramp whose slope mean is a known constant and whose
slope sigma is zero (SL_RAMP_E6), a constant signal where both are zero
(SL_CONST_E6), a sine with fractional output formats (SL_SINE_E7_Q),
mean-only and sigma-only configurations (SL_ONLY_MEAN, SL_ONLY_SIG, which
also exercise the two different tail lengths), IN_DV gaps inside the
accumulation to pin the “previous ACCEPTED sample” rule (SL_DVGAP_E6), and
an EXP that changes half way through a block (SL_EXPCHG). The status
outputs are checked clock by clock against the contract above, and the
tail length is cross-checked at compile time between the C macro, the VB
TailClocks function and the golden generator - the testbench refuses to
build if the three disagree.